Gen-TTS: Expressive Multi-Speaker Audio, Podcasts & Voice Synthesis
A command-line interface for Google Gemini Native Text-to-Speech (TTS) capabilities (gemini-3.8-flash-tts), supporting 30 expressive voices, multi-speaker dialogues, and AI-written podcasts, debates, and summaries.
uv tool install --python 3.12 git+https://github.com/charles-forsyth/generate-tts.git
Key Capabilities
Designed and tuned for modern terminal workflows and automated pipelines.
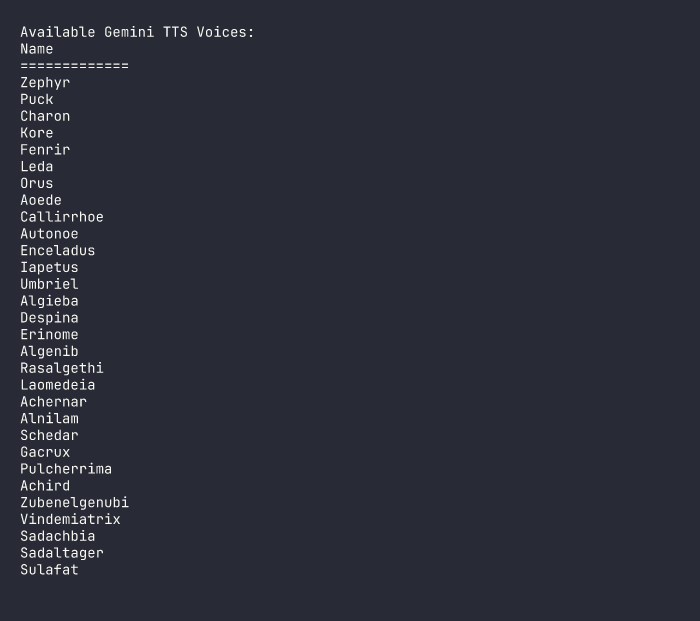
30 Expressive Gemini Voices
Direct access to Charon, Kore, Puck, Zephyr, Fenrir, and all 30 native expressive Gemini voice models.
Multi-Speaker Scripting
Synthesize dialogues with Speaker: Text tagging and custom speaker-to-voice assignments.
7 Built-In Producer Modes
Automatically transform raw text into a podcast, summary, debate, interview, storyteller, news, or lecture.
Topic-to-Audio Transcript
Have Gemini author the script and synthesize multi-speaker audio in a single automated command.
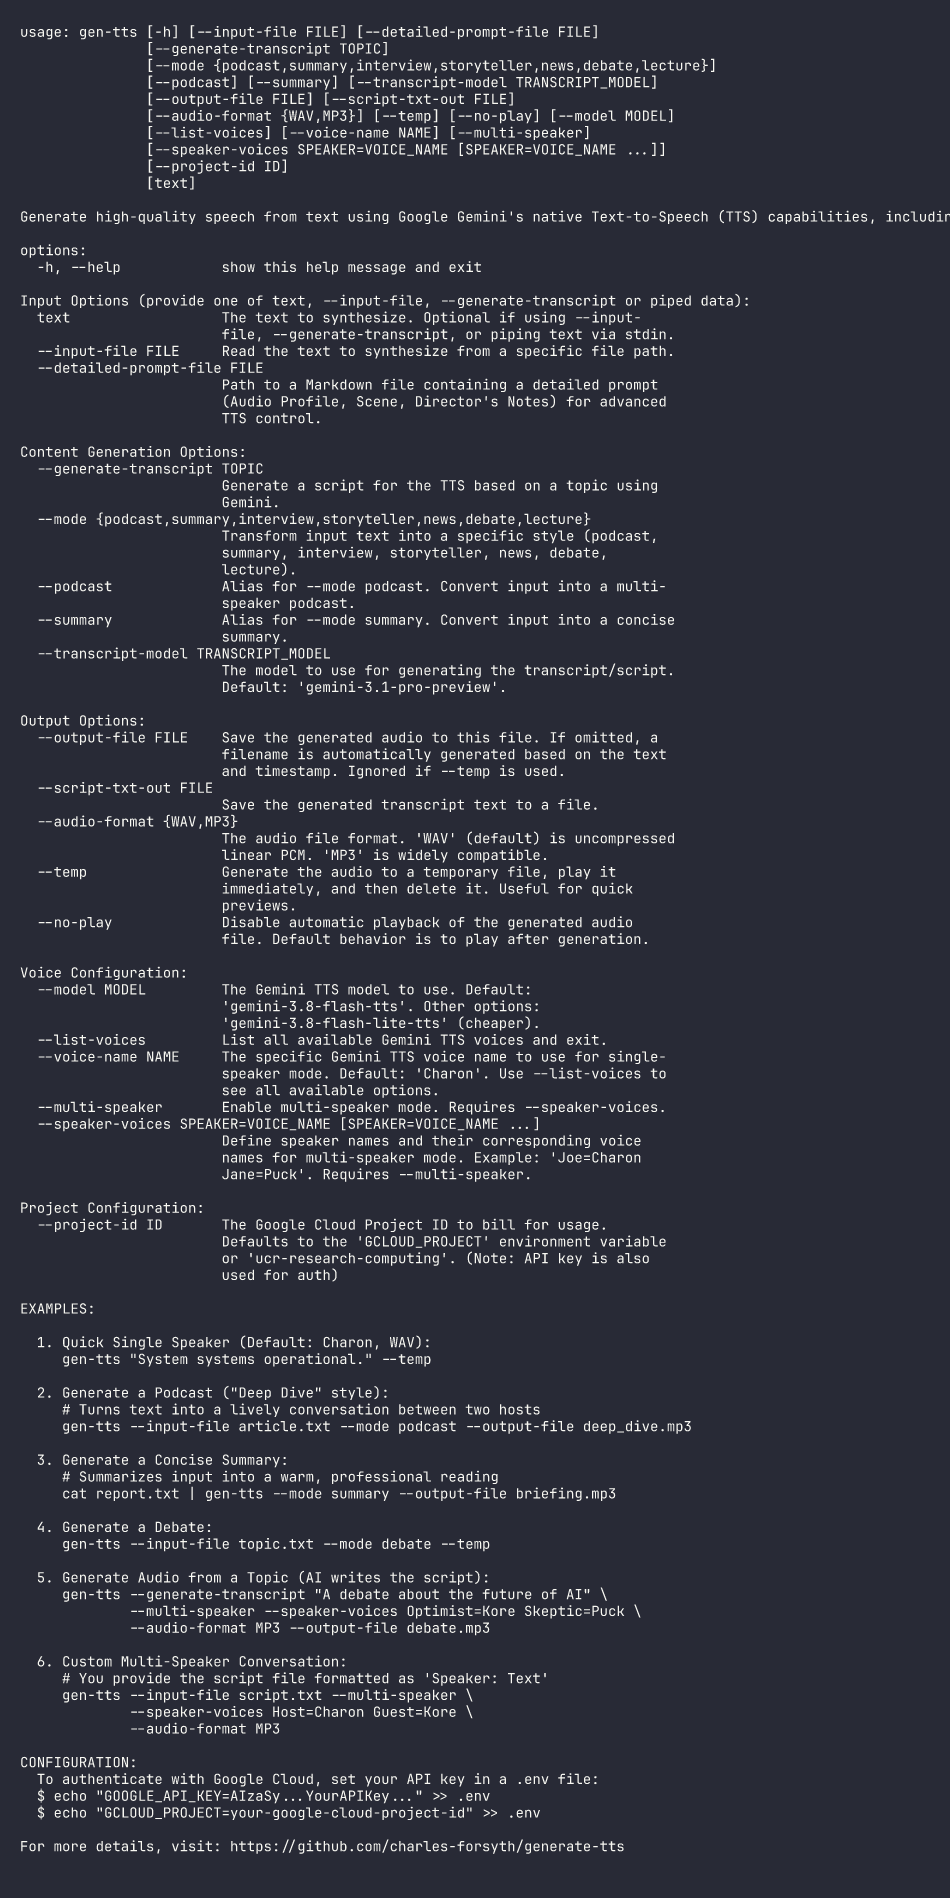
Terminal Showcase
Real, unmodified terminal outputs captured directly from the CLI engine.
Usage Examples
Quick command recipes for terminal operations.
Quick Speech Synthesis
Synthesize text and play immediately:
Deep Dive Podcast Mode
Transform article into two-host conversation:
List All 30 Voices
Inspect all available voice identities:
Topic to Multi-Speaker Debate
AI writes and speaks an audio debate:
Citation

If you use this tool in your research or applications, please cite:
Forsyth, C. E. III (2026). Gen-TTS: Gemini Native Audio Generation CLI (Version 0.2.2) [Computer software]. University of California, Riverside. https://doi.org/10.5281/zenodo.23755689
@software{forsyth2026generate_tts,
  author       = {Forsyth, Charles E. III},
  title        = {Gen-TTS: Gemini Native Audio Generation CLI},
  version      = {0.2.2},
  year         = {2026},
  publisher    = {Zenodo},
  affiliation  = {University of California, Riverside},
  doi          = {10.5281/zenodo.23755689},
  url          = {https://github.com/charles-forsyth/generate-tts}
}